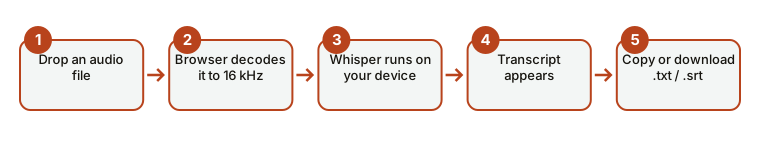
1. Decoding
Your browser's Web Audio API decodes the file and converts it to 16 kHz mono, the format Whisper expects. Stereo files are mixed to mono.
2. The model
The transcriber uses OpenAI's open-source Whisper speech recognition model, converted to the ONNX format and run with Transformers.js and ONNX Runtime Web (WebAssembly). Two sizes are offered: Fast (Whisper tiny, about 40 MB) and More accurate (Whisper base, about 80 MB). English uses the English-only versions.
3. Model download
The first run downloads the model files from the Hugging Face model hub. The progress bar shows the real download. Your browser caches the files, so later runs start quickly and can work offline after the page loads.
4. Transcription
Audio is processed in 30-second windows with overlap, and the text streams into the box as it is recognized. Speed depends on your device: a recent laptop usually runs the Fast model faster than real time; phones are slower.
5. Export
Copy the text, download it as .txt, or download .srt captions built from the segment timestamps. The first download is free. A later download asks for your name and email, then downloads the file in the browser and emails the same file to you.
Limits
- No speaker labels.
- Files up to about two hours.
- Accuracy drops with noise, music, cross-talk, and heavy accents.
- Needs a current browser with WebAssembly and Web Workers.